YOLOv11 PyTorch TXT
Overview
YOLOv11 PyTorch TXT is the format used by the YOLO11 object detection model.
Format Description
Below, learn the structure of YOLOv11 PyTorch TXT.
Each image has one txt file with a single line for each bounding box. The format of each row is
class_id center_x center_y width height
where fields are space delimited, and the coordinates are normalized from zero to one.
Note: To convert to normalized xywh from pixel values, divide x (and width) by the image's width and divide y (and height) by the image's height.
001.txt
1 0.617 0.3594420600858369 0.114 0.17381974248927037
1 0.094 0.38626609442060084 0.156 0.23605150214592274
1 0.295 0.3959227467811159 0.13 0.19527896995708155
1 0.785 0.398068669527897 0.07 0.14377682403433475
1 0.886 0.40879828326180256 0.124 0.18240343347639484
1 0.723 0.398068669527897 0.102 0.1609442060085837
1 0.541 0.35085836909871243 0.094 0.16952789699570817
1 0.428 0.4334763948497854 0.068 0.1072961373390558
1 0.375 0.40236051502145925 0.054 0.1351931330472103
1 0.976 0.3927038626609442 0.044 0.17167381974248927
The `data.yaml` file contains configuration values used by the model to locate images and map class names to class_id's.
data.yaml
train: ../train/images
val: ../valid/images

nc: 3
names: ['head', 'helmet', 'person']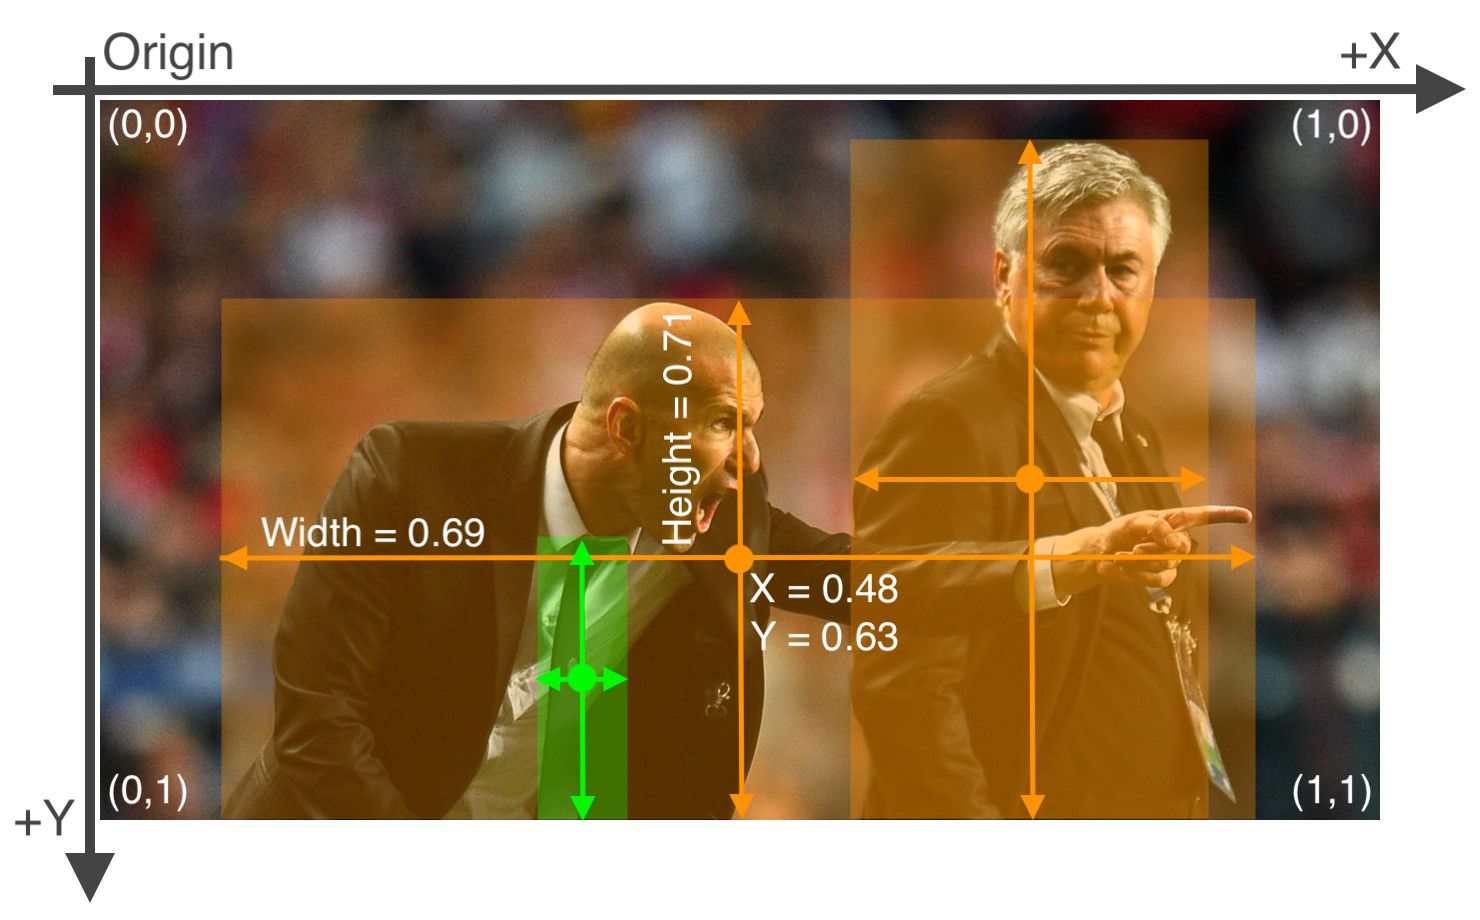
Convert Data from YOLOv11 PyTorch TXT
Convert Data to YOLOv11 PyTorch TXT
- COCO JSON
- Cogniac
- CreateML JSON
- Google Cloud AutoML Vision CSV
- IBM Cloud Annotations JSON
- Kaggle Wheat CSV
- LabelBox JSON
- LabelBox Video JSON
- LabelMe JSON
- Marmot XML
- Multiclass Classification CSV
- OIDv4 TXT
- OpenImages CSV
- PaliGemma JSONL
- Pascal VOC XML
- RetinaNet Keras CSV
- Sagemaker GroundTruth Manifest
- Scale AI JSON
- SuperAnnotate JSON
- Supervisely JSON
- Tensorflow Object Detection CSV
- Udacity TXT
- Unity Perception JSON
- VoTT CSV
- VoTT JSON
- YOLO Darknet TXT
- YOLO Keras TXT
- YOLOv10 PyTorch TXT
- YOLOv8 PyTorch TXT