OpenAI GPT5 min read
How to Use GPT-4 To Extract Handwritten Text from Images
 Nathan Y.Jul 5, 2024
Vision language models (VLMs) are multimodal models that read images and text together, so you can ask questions about a photo, extract data or detect objects from a prompt. These posts compare VLMs, benchmark them and show how to use them in production.
Nathan Y.Jul 5, 2024
 Nick HerrigJun 21, 2024
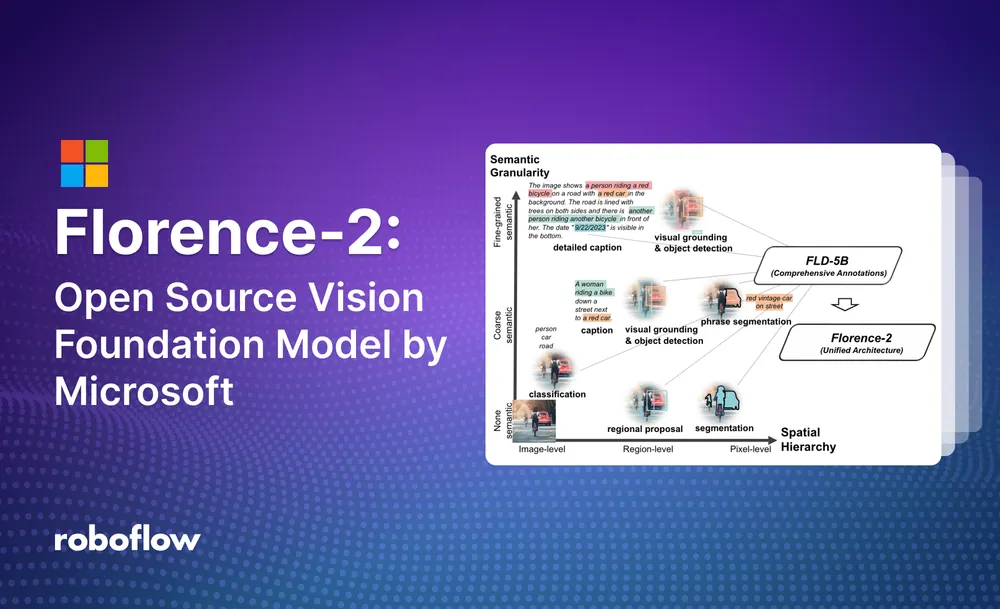
 Piotr SkalskiJun 20, 2024

 Leo Ueno and Trevor LynnMay 15, 2024
 Leo Ueno and Trevor LynnMay 14, 2024
 Timothy MApr 30, 2024
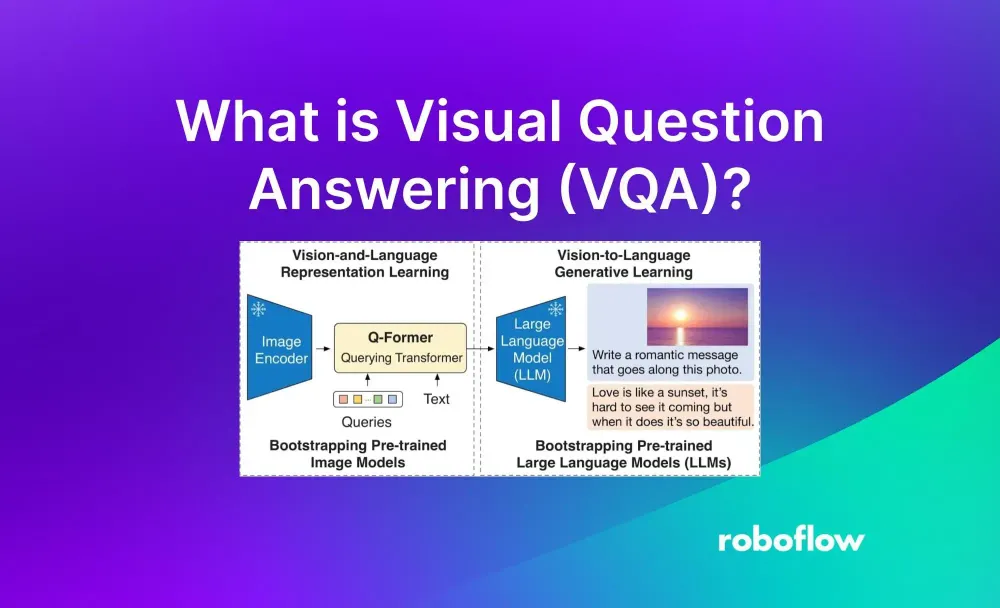
 Petru P.Mar 13, 2024
 James GallagherMar 5, 2024
 James GallagherMar 3, 2024
 James Gallagher and Piotr SkalskiFeb 8, 2024
 James GallagherFeb 2, 2024
 James GallagherJan 5, 2024
 Piotr SkalskiDec 20, 2023
 James GallagherDec 20, 2023
 James GallagherDec 14, 2023
 James GallagherDec 13, 2023