AI Visual Inspection7 min read
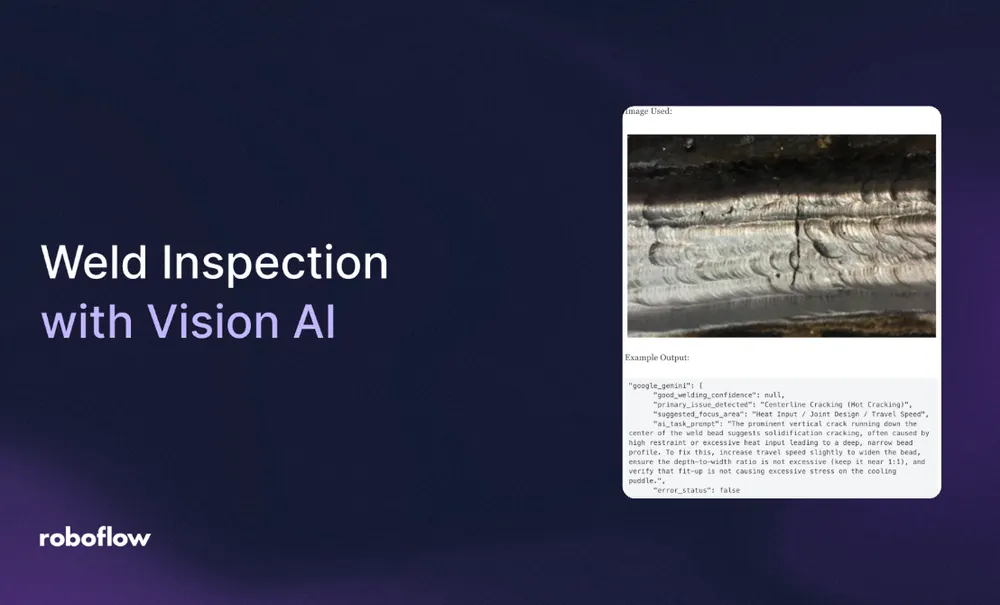
How to Build an Edge Vision System for Weld Inspection
 Contributing WriterFeb 10, 2026
Vision language models (VLMs) are multimodal models that read images and text together, so you can ask questions about a photo, extract data or detect objects from a prompt. These posts compare VLMs, benchmark them and show how to use them in production.
Contributing WriterFeb 10, 2026 Contributing WriterFeb 4, 2026
 Contributing WriterJan 26, 2026

 Timothy MJan 22, 2026

 Contributing Writer and Dikshant ShahJan 21, 2026
 Timothy MJan 13, 2026

 Erik KokaljJan 8, 2026
 Contributing WriterDec 31, 2025
 Contributing WriterDec 30, 2025
 Contributing WriterDec 10, 2025
 Contributing WriterDec 10, 2025
 Contributing WriterNov 5, 2025
 Contributing WriterOct 10, 2025
 Timothy MSep 30, 2025
 Dikshant ShahSep 16, 2025
 Dikshant ShahSep 8, 2025